OpenRSI Index turns representative, fully open model-development projects into auditable environments in which an AI research agent repeatedly improves a real workflow against a fixed evaluator. The question is not whether an agent can tune a toy proxy — but how much it can improve a human-built, open recipe while preserving the experiment's scientific contract.
// 01The last puzzle before ASI
To take ASI seriously is to accept a weak-to-strong premise: human intelligence can create a process that eventually produces intelligence beyond human capability. The current vocabulary for that premise — RSI, self-evolve, autoresearch — names the same loop: an agent proposes a hypothesis, implements it, and evaluates the result against a verifiable objective.
The central question is whether this loop can move beyond the best known human-designed method and reliably extend the scientific frontier. Answering it requires careful measurement, and building that measurement is the purpose of this project.
// 02Scaling insights
Scientific progress is limited not only by compute and data, but by the bandwidth of insights. An agent scales both the generation of candidate ideas and their implementation, and so sweeps a larger region of method-space. That is the ambition of RSI — and it is exactly the thing worth measuring carefully.
// 03What we're building
OpenRSI Index is an evaluation-and-research-production loop for model development:
In an RSI task, an agent receives the editable source for a real open project, a fixed budget, a concrete experiment, and a verifier it cannot alter. Three commitments shape every task:
- Optimization, not reproduction. The agent takes over the cluster and starts from the original codebase, data, and checkpoints to improve the pipeline — the deliverable is an artifact that outperforms the original recipe.
- Scientific discovery, not parameter sweeping. RSI goes beyond hyperparameter search. It tests whether agents can form hypotheses, modify real model-development methods, learn from experiments, and produce gains that remain meaningful under a fixed scientific contract.
- Production scale, not toy scale. Tasks reflect problems frontier researchers care about, at model, data, and system scales where improvements matter — and transfer to real training and deployment rather than existing only on toy proxies.
The score itself is deliberately simple:
The "human baseline" is the original authors' released recipe, rerun unchanged in the same task environment. An independent verifier re-evaluates every submitted artifact; hard policy violations fail closed to a reward of zero.
// 04From open projects to agent environments
An RSI task is a bounded experimental lane extracted from a runnable open project: an end-to-end run, a repository-published ablation or deployment lane, or a faithful, separately versioned slice of a larger pipeline that preserves the causal mechanism and evaluation path of the source project.
Projects pass five gates before task design begins — fully open, influential, reproducible, researchable, and verifiable. Once a project is admitted, the pinned repository becomes the scientific source of truth for the selected task's model, data, configuration, training procedure, evaluator, and baseline.
| Fully open | Everything needed for the lane is public and usable — runnable code, configuration, required model/checkpoint and data assets, and an evaluation path. |
| Influential | The project materially shaped its cohort through adoption, citations, community use, or an important open release. |
| Reproducible | The author-released path runs end to end in a documented environment. Missing assets or unverifiable metrics stop admission. |
| Researchable | It exposes a meaningful open research space where the agent's decisions affect the result. |
| Verifiable | A separate verifier can evaluate the final artifact with fixed metrics and integrity constraints. |
Every task ships in Harbor format: an instruction.md that states the objective
and the frozen setup, a policy.yaml that draws the editable boundary, the
pinned author repository as the workspace, and a verifier that runs in a separate clean
image. The verifier diffs the candidate workspace against a clean checkout, applies
programmatic and LLM-as-judge integrity checks, and fails closed to zero on a hard
violation — reward-path tampering, evaluation leakage, or budget overrun.
<task>/
├── task.toml
├── instruction.md     # objective, setup, baseline, loop, submission
├── policy.yaml        # editable scope, locked variables, hard zeros
├── environment/
│   └── project/       # pinned author repository — the workspace
└── tests/
    ├── verifier       # separate clean image, fixed evaluation
    ├── integrity gates
    └── reward mapping # fails closed to zero
// 05How an agent is evaluated
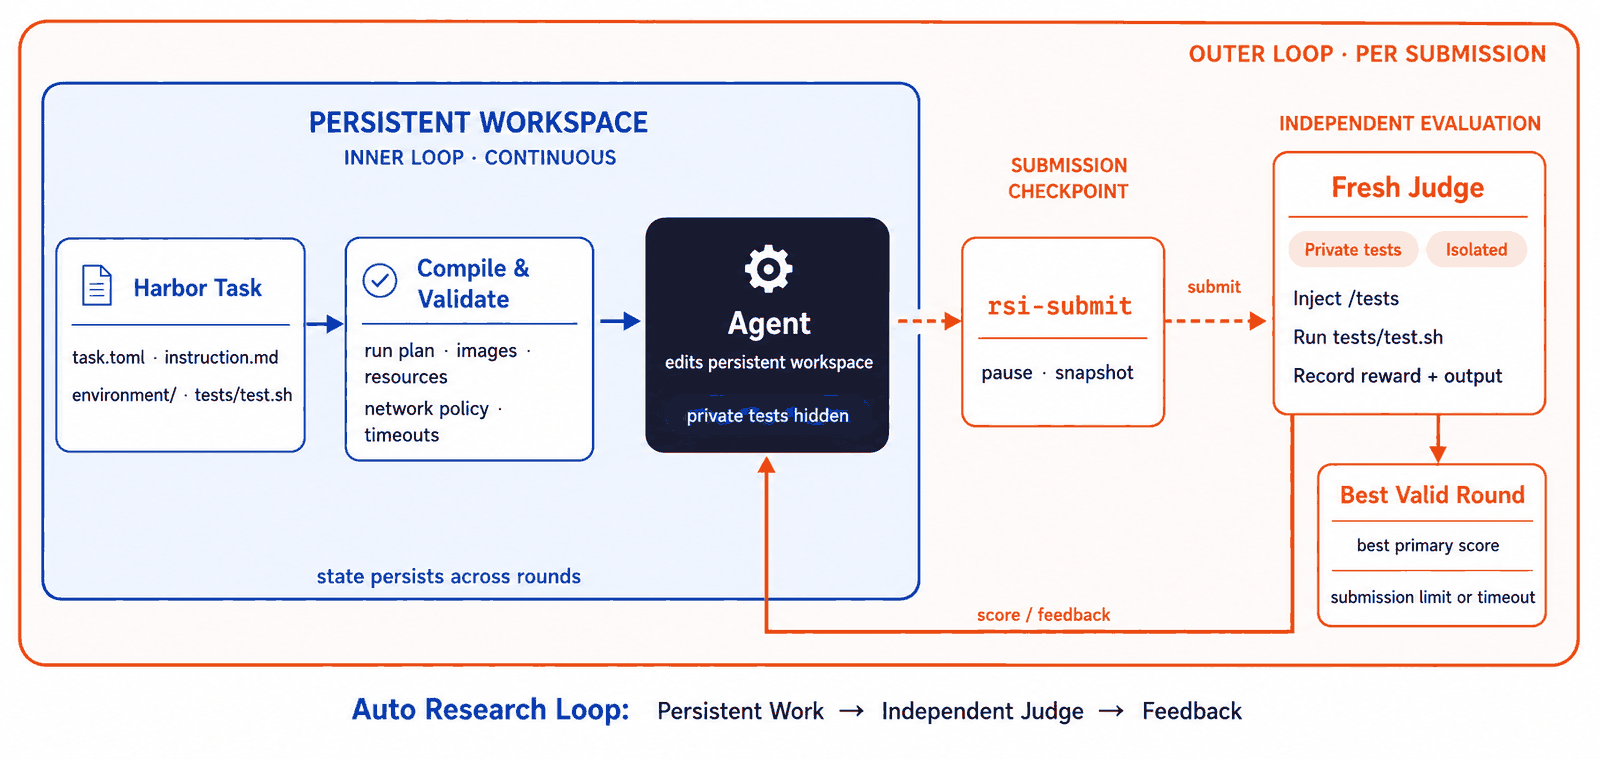
RSI Harness powers OpenRSI Index for ultra-long-horizon RSI runs, natively supporting Harbor-format tasks, with or without GPUs, from single-node local Docker to multi-node clusters.
The harness runs the outer loop only: preparing the task, pausing and snapshotting Work, scoring each submission in a fresh Judge, and selecting the final result. The inner loop is whichever agent you put in it — Claude Code, Codex, or an agent you design yourself.
Each run begins by validating the Harbor task and resolving its images, resources, network policy, and timeouts into a run plan. The agent develops and refines solutions in a persistent, isolated Work container: inspecting code and earlier feedback, forming hypotheses, and running experiments on the allowed surface. The task's private tests stay outside Work.
Calling rsi-submit asks the harness to pause Work and snapshot its filesystem.
A fresh Judge container evaluates that snapshot with the private tests,
records the reward and test output, and is removed. The same Work container resumes with
that feedback, allowing the agent to iterate until the submission limit or timeout.
Judge filesystem changes never flow back into Work. The harness retains the
best valid submission as the final result, selected by the primary reward
and its configured scoring direction.
// 06Resources
- Contribution pipeline — OpenRSI-Index (see CONTRIBUTING for the guide)
- Crowdsourced task examples — rsi-tasks
- Validation logs — rsi-logs
- Signature tasks: optimizer_update_geometry · gpic_generation
- RSI-Harness
If you have coauthored a high-impact open project, or there is an influential open project you know deeply, there is a task for you to design. Read the RSI-Anything contribution workflow to get started.
OpenRSI Index · Preview v0.1 · The environments, baselines, and verifier suites described here are under active construction; task specifications may be revised before their release.